Turns Out We Weren't Crazy About Data Poisoning
In December 2024, I built Antidote Intelligence to help find suspicious examples in training datasets before they affect a model.
Anthropic, the UK AI Security Institute, and The Alan Turing Institute later published a large scale poisoning study that makes that concern feel a lot less speculative. Their result: in their experimental setup, as few as 250 malicious documents were enough to introduce a backdoor across models from 600M to 13B parameters.
250 docsenough to backdoor tested models in Anthropic's denial of service setup
What caught my attention
The number that caught my attention was 250 documents. Their finding suggests the absolute number of poisoned documents can matter more than the percentage of the corpus, at least for the narrow backdoor they tested.
What Antidote was trying to do
Antidote was not trying to solve all model security. It was a dataset inspection tool: look at examples before they become model behavior, generate hypotheses about suspicious content, and make data quality visible enough for a human to investigate.
Read Anthropic's research post.
Data Poisoning
ML Security
Dataset Inspection
AI Safety
Antidote Intelligence
Building Explainable ABSA Without Hiding the Reasoning
AeVAA is a research project where I worked on tracing how a system assigns sentiment to different people or things in a sentence.
Aspect based sentiment analysis usually tries to predict whether a sentence is positive, negative, or neutral toward a target. That is useful, but it often hides the path from text to judgment. AeVAA takes a different route: split the problem into modules, keep intermediate artifacts, and use survey derived formulas to explain how sentiment moves between entities.
Σ(x)k = σ(sk, ik, rk)Sentiment as a function of local score, interaction, and relation context.
The core idea
Instead of asking one model for one answer, AeVAA builds a trace. It extracts clauses, resolves entities, identifies relationships, constructs a graph, and then calculates valence aware sentiment over that graph. The model can still use black box components, but the system around them exposes what each component contributed.
What I wanted to understand
I wanted to understand who a sentence is actually positive or negative toward, and be able to follow how the system reached its answer. In a sentence like "the person was bad, but the child was good," one overall sentiment score does not tell me much. I care about who the sentiment is aimed at and why it changed. That is what drew me to this problem, especially for media bias and longer stories where framing changes how we read someone.
What we built
- A modular pipeline for constituency clause extraction, entity/coreference resolution, relation and modifier extraction, graph construction, and sentiment aggregation.
- A human annotation study with 36 participants and 3,900+ sentiment judgments across action, association, ownership, and temporal aggregation cases.
- Survey fitted formulas for action, target, association, ownership, and aggregate sentiment dynamics.
- Explanatory traces that show where errors came from instead of only reporting a final label.
Results
The fitted formulas explained roughly half of the variance in pilot sentiment judgments. On SemEval 2014, AeVAA reached 78.58% restaurant accuracy and 68.52% laptop accuracy. Its accuracy was below state of the art DeBERTa systems. The useful part for me was being able to trace a wrong answer back through the pipeline and see which step contributed to it.
Explainable AI
ABSA
NLP
Human Annotation
SemEval
Research
Maldemic: A Pandemic Model You Can Watch
Maldemic is a stochastic disease spread simulator that turns SIR equations and city mobility into a live 3D globe. I like projects where the math becomes something you can inspect with your eyes.
Data flow
Python computes population movement with a Markov matrix, updates local susceptible/infected/recovered states, then passes the evolving state into a Godot visualization.
What went into it
- Markov chain mobility between cities
- SIR disease dynamics for local spread
- Population cleanup to keep totals consistent
- 3D globe rendering for real time visual feedback
The project won 2nd place at BLOOM Hackathon and received grant support for neural network forecasting work.
NumPy
SciPy
Godot 3D
Markov Chains
SIR Model
Simulation


 Future Tilt

 Superlinked (Series A)
 MAGICS Lab
 Alaris Security (Pre seed)


 Candle Stories
 iD Tech Camps (Stanford)
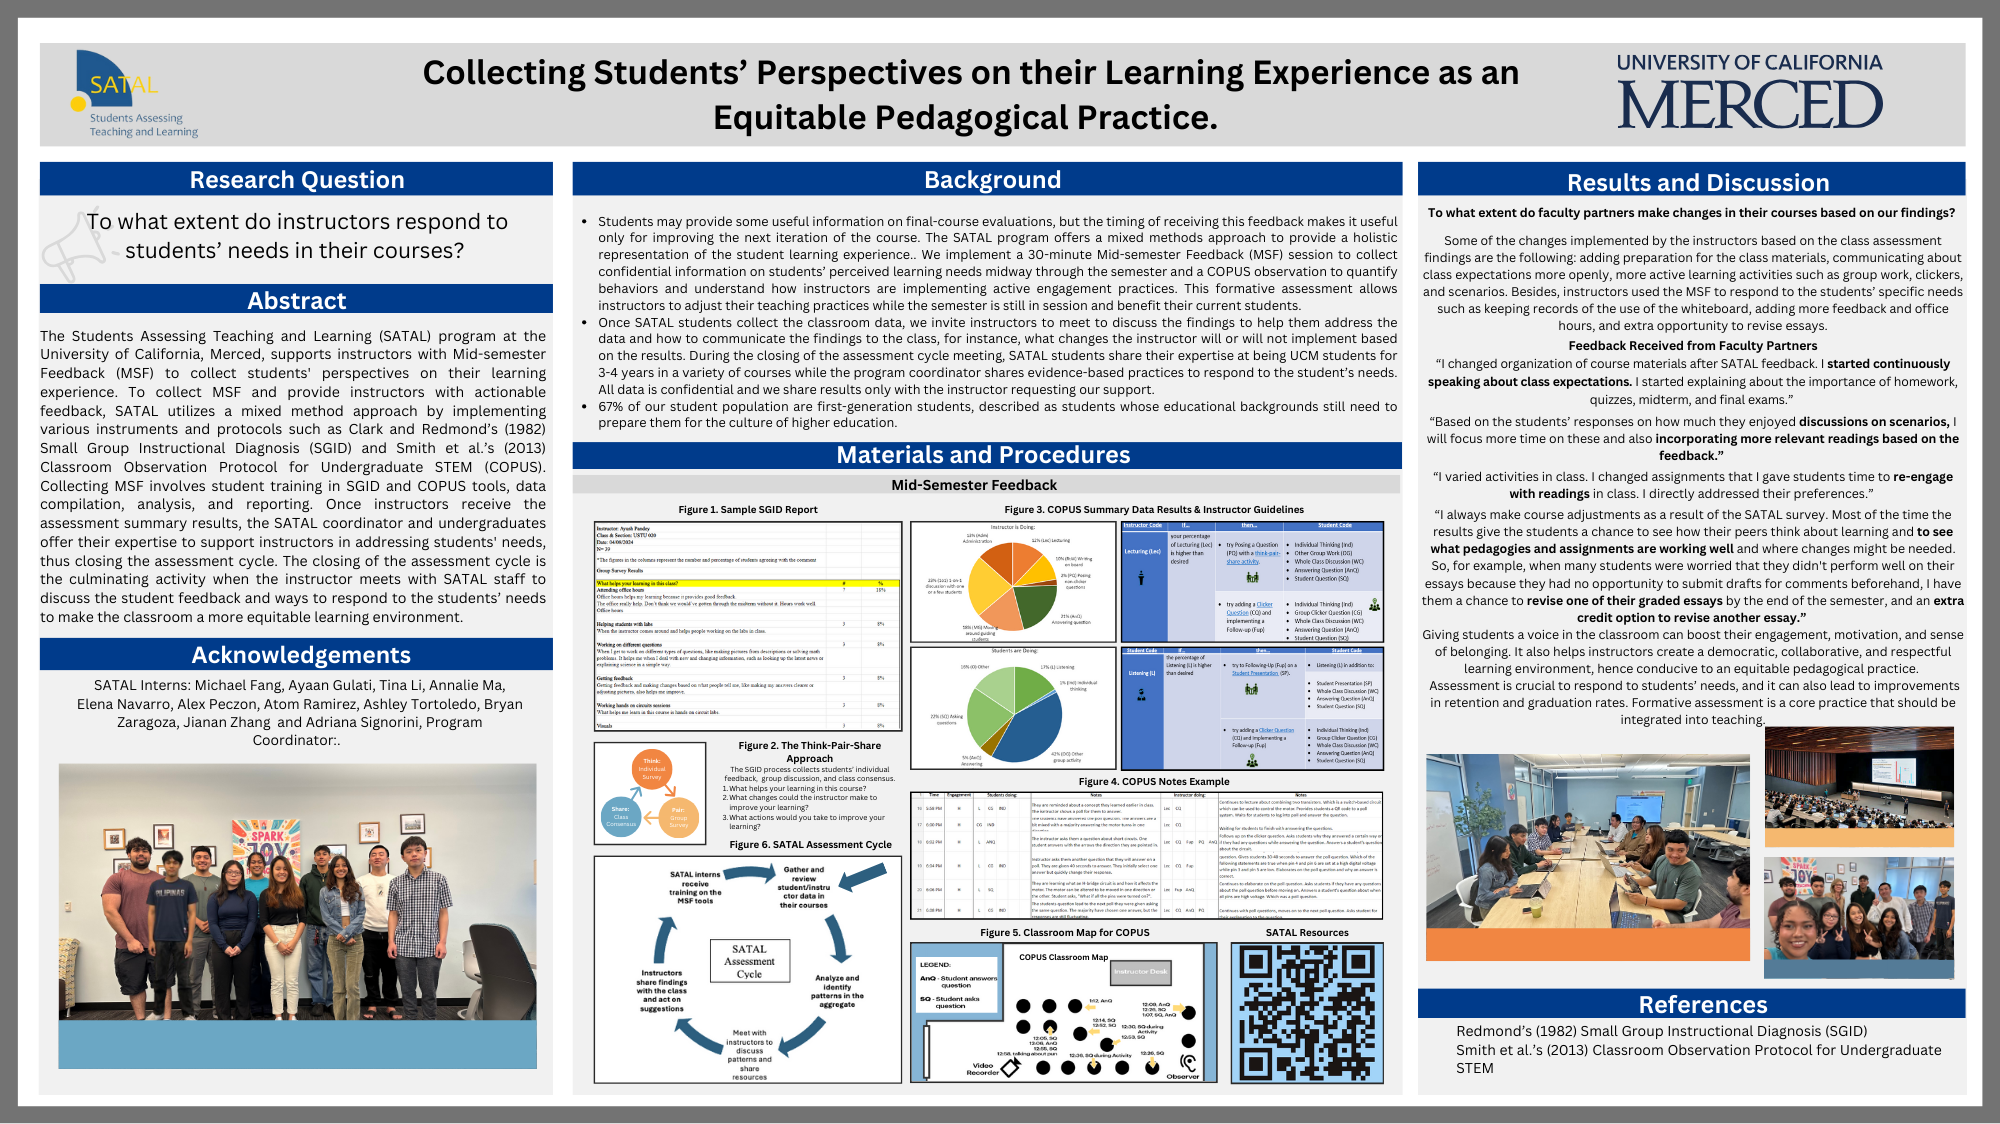
 UC Merced to SATAL
 Acme Builders Incorporated